The prompt is rarely the problem
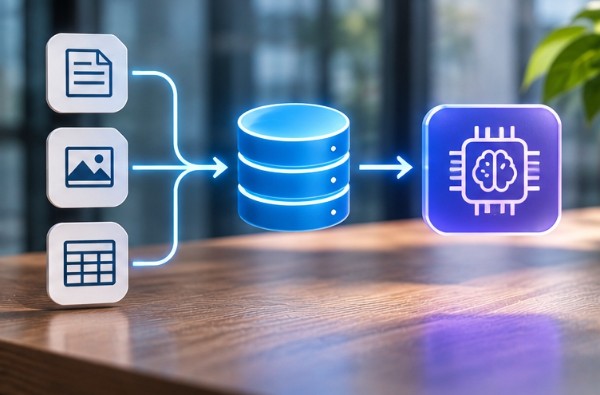
Internal copilots usually fail for an unglamorous reason: the corpus. The model is asked to answer from documents that are out of date, duplicated across four systems, or missing the one policy that actually governs the question.
Better prompting cannot fix a corpus that disagrees with itself.
What goes wrong, in order of frequency
- Duplicates with different answers. Three versions of a policy, two of them superseded, none of them marked as such.
- No access model. Retrieval returns a document the person asking is not allowed to read.
- Unstructured does not mean unmanaged. Nobody owns the folder, so nobody removes anything.
- Chunks that cut mid-table. The number and its heading end up in different chunks and the answer is confidently wrong.
Treat the corpus like a data product
Give it an owner, a refresh schedule, a definition of what belongs in it, and a way to mark a document as superseded. That work is unexciting and it determines whether the thing is useful.
If you would not trust the folder to answer a question, the model will not fix it.
Evaluate against real questions
Collect fifty questions people actually asked last quarter, with answers reviewed by someone who knows the domain. Run them on every change. Without this you are shipping on vibes.
Always cite
Every answer should point at the source document. It makes errors visible, gives the reader a way to check, and changes the tool from an oracle into a search engine that writes — which is the thing people needed anyway.
Tasha Bramley
Head of Machine Learning